
Introduction
Table of Contents
Data is considered the most valuable asset for any contemporary business. Enterprises collect vast amounts of data from their websites, CRMs, applications, customer registration forms, purchases, social networks, and other sources. However, a significant quantity of data does not equal valuable and useful data.
Poor-quality data can consist of duplicate entries, missing values, wrong information, inconsistent data formats, obsolete entries, and other mistakes. Utilizing such data during reports, analysis, marketing, or decision-making by businesses may result in obtaining wrong insights and losses.
That is why the process of data cleansing is so important.
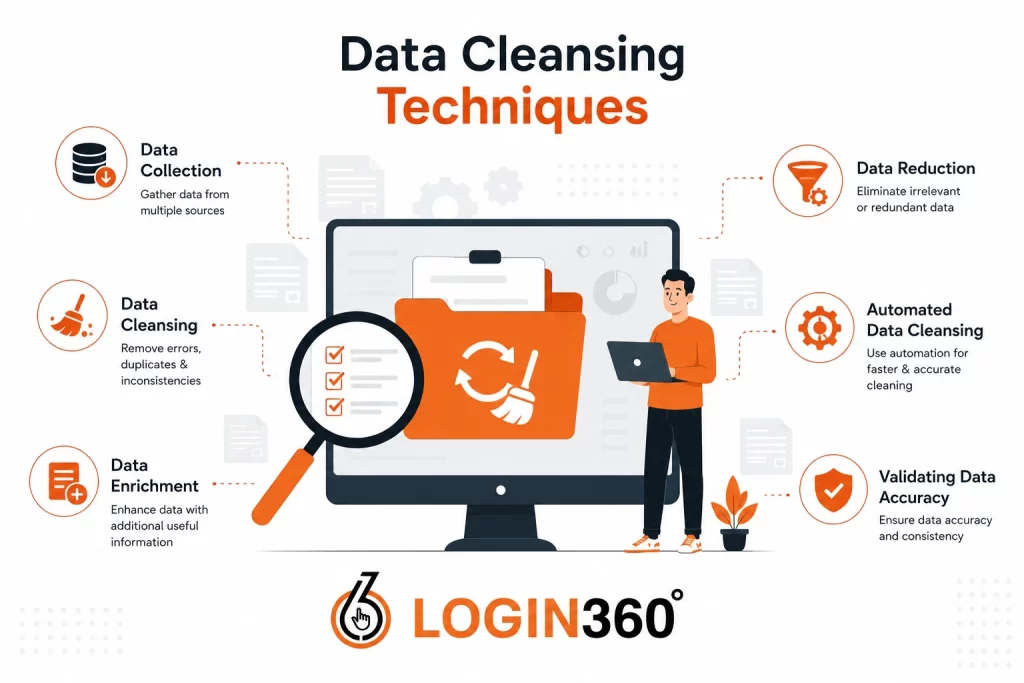
Data cleansing, or cleaning, is the procedure of detecting and correcting inaccurate, incomplete, inconsistent, duplicate, and irrelevant data. Using proper data cleansing techniques, companies can enhance the quality of their data and create the basis for analysis.
This guide is about the most essential data cleansing techniques, the importance of data quality, and creating a successful data cleansing process.
What Is Data Cleansing?
Data Cleansing is the process of checking and correcting data that is wrong, missing, duplicate, inconsistent, or outdated in a dataset.
Consider, for instance, a customer data set that includes the following:
John Mathew – Kochi – 9876543210
John Mathew – Cochin – 9876543210
John Mathew – Kochi – 9876543210
This can be a single customer who appears more than once with varying locations. In case such data is not cleansed, the company will end up counting the same customer more than once.
Cleansing data helps in such instances.
Cleansing data is not about removing unneeded data. Instead, the aim is to ensure that the data is accurate, consistent, complete, relevant, and usable.
Why Is Data Cleansing Important?
Companies make use of data in order to make decisions. With inaccurate data, even advanced tools would not be able to provide accurate results.
The following points highlight the benefits of data cleansing:
1. Increases Accuracy of Data
Inaccurate data impacts reports, dashboards, customer details, and also the business analysis. Cleaning up inaccurate data will increase accuracy.
2. Removes Duplicate Data
Duplicate data can lead to wrong customer figures, sales numbers, and inventory details. It needs to be removed in order to have one record.
3. Assists Decision Making
Business leaders make decisions on the basis of accurate data to spot trends and take decisions. Accurate data will assist in better decision-making.
4. Time Saving
An employee spends a lot of time on manual correction of errors. The time spent by employees can be saved.
5. Better Analytics
Accurate datasets are needed for data analysts and data scientists before analyzing and building models.
7 Essential Data Cleansing Techniques
There are many ways that an organization can enhance the quality of its data. Each approach would depend on the kind of dataset, the business needs, and the data source.
1. Deleting Duplicates
Duplicated data is one of the major data quality issues.
The reason behind having duplicated data in the database is that the company collects data from various sources. In some cases, a client may fill out forms on a website and then another form using a slight variation of his/her name.
Some duplicate detection approaches will match the following fields:
Name
E-mail address
Phone number
Client identification number
Address
Transactions
Fuzzy matches are useful when there are some variations in the data record.
2. Dealing With Missing Values
Missing values constitute yet another major problem in data analysis.
Imagine a customer data set like this one:
Customer Age Location Purchase
A 25 Kochi ₹5,000
B — Kochi ₹3,000
C 31 — ₹7,000
Depending on the way the data set will be used, these missing values might impact the results of the analysis.
Here are some common solutions to this problem:
Deleting the record when possible
Substituting the missing values with a relevant default
Finding the average, median, or mode
Predictive calculation
Explicitly marking the missing values
The method to be applied will depend on the reason behind the missing data and its importance.
Unnecessary filling of missing fields might lead to more complications rather than solving the problem.
3. Standardization of Data Formats
The data obtained from various systems is normally represented in varied formats.
For instance:
Date formats
02/09/2026
09-02-2026
2026-09-02
Name
John Mathew
JOHN MATHEW
john mathew
Locations
Kochi
Cochin
KOCHI
The standardization process ensures that these varied formats are transformed into a uniform one.
The organization may choose to standardize:
Date formats
Telephone numbers
Addresses
Names
Money
Measurement units
Capitalization of text
Country codes
4. Fix Misleading Data
There might be some cases when the information presented is wrong owing to various reasons such as human mistakes, old data, or technical problems.
For instance, there can be too few digits in a telephone number, a typing error in an e-mail address, or wrong designation of the product category.
The data validation technique can help detect misleading data.
For instance, one can check if the e-mail address is in the right format, whereas numerical values can be checked against the appropriate ranges.
However, companies should pay attention to this process and avoid making any changes to misleading data without checking it first.
5. Validate the Data According to Rules
Data validation is the process by which data is made to conform to a set of rules.
For instance:
- The age must not be a negative value.
- A percentage must not go outside the usual range.
- A mandatory customer ID cannot be empty.
- An email address must conform to the expected format.
- The date of a transaction must be logical within the business environment.
- Validation may be done at the time data enters the system, or it can be done during cleansing.
- It is better to prevent bad data from entering the database than to clean it many times later.
6. Detecting and Handling Outliers
An outlier is a data point that stands out from other data points by being significantly different from them.
For instance, if most transactions by customers are in the range of ₹500 to ₹10,000 and there is one data point showing a transaction of ₹50,00,000.
This data point might either be:
A legitimate transaction worth a large sum of money
Data input error
Unit conversion error
Fraudulent transaction
System error
Consequently, an outlier cannot be removed simply because it is an outlier.
Techniques for detecting outliers include standard deviation, interquartile range, and clustering.
7. Deleting Irrelevant or Outdated Information
Not all information collected will be relevant to all types of analyses.
It could include out-of-date customer data, products that have been discontinued, test data, or information that is no longer current.
Deleting irrelevant data can help make the dataset easier to handle and analyze.
However, the deletion of data should be done with care since some of the information might be valuable for compliance, auditing, trend analysis, etc.
Information can be archived instead of deleting it permanently.
Simple Steps in Data Cleansing
A typical data cleansing process should contain several simple steps.
Step 1: Understanding the Data
Nothing should be done until one comprehends the source of the data, its meaning, and where it will be utilized.
Step 2: Profiling the Data
Profile the dataset to discover problems, including:
Missing values
Duplicate records
Invalid data
Inconsistent formatting
Outliers
Step 3: Set Data Quality Standards
Define good data clearly.
For example, determine the format of the phone numbers, dates, customer ID numbers, and other fields.
Step 4: Cleansing the Data
Cleansing of data with the help of the suitable methods.
Step 5: Validating the Data
Verify that the data is of high quality as per the set standards.
Step 6: Monitoring Data Quality
Data cleansing is not a one-time activity; organizations receive data all the time.
Data Cleansing Tools and Technologies
It is possible for organizations to use various types of technologies for data cleansing and transformation based on the requirements of the organization.
Some of the popular techniques are:
SQL for detecting duplicates, filtering rows, and transforming database data
Python for automation of data cleaning and complex processing
Excel for small data sets and simple data cleaning
ETL tools for data cleansing while extracting, transforming, and loading
Data quality software for automation of data validation, monitoring, and governance
One of the popular uses of Python is for detecting missing values, duplicates, and transforming columns in the Pandas library.
Common Data Cleansing Mistakes to Avoid
When conducting data cleaning, companies should refrain from assuming that all anomalies are mistakes.
Some mistakes to look out for are:
Deleting information without understanding it:
An anomaly might not be an anomaly; it might represent a valid business case.
Putting a default value of zero for all missing fields:
Missing does not automatically equal zero.
Cleaning information without keeping records:
It is essential to note what has been changed, why it has been changed, and when it has been transformed.
Neglecting the reason behind the problem:
In cases where there are recurring errors, the company needs to investigate the source of the problem.
Cleaning the data as a single task:
The quality of the data could get worse after information is introduced into the system.
Data Cleansing vs. Data Transformation
Data Cleansing and Data Transformation
While these concepts have something in common, they do not mean the same thing.
Data cleansing aims to enhance the quality of data through correction of errors, duplicates, missing data, and other types of inconsistencies.
On the other hand, data transformation seeks to change the data in order to make it usable or applicable to some other purpose.
For instance, changing data from 02/09/2026 to 2026-09-02 can be viewed as a transformation, whereas data cleaning will involve fixing an invalid date like 45/19/2026.
Conclusion
Quality data is crucial for accurate analysis, reporting, automation, and decision-making within a business. However, very often, data does not come in the right form.
It is necessary for businesses to have good methods of data cleansing to detect duplicates, solve issues of missing data, standardize, correct, validate, explore, and deal with unnecessary data.
What needs to be remembered is that the cleansing of data is not only a process of resolving existing problems. It is equally important to introduce standards to avoid receiving low-quality data.
Data cleansing is an important aspect for those who want to improve their analytical skills. Good data helps to analyze information, recognize trends, and create insights.
Ready to Build Better Data Skills?
Login360 can help you build industry-relevant skills through practical, career-focused learning.